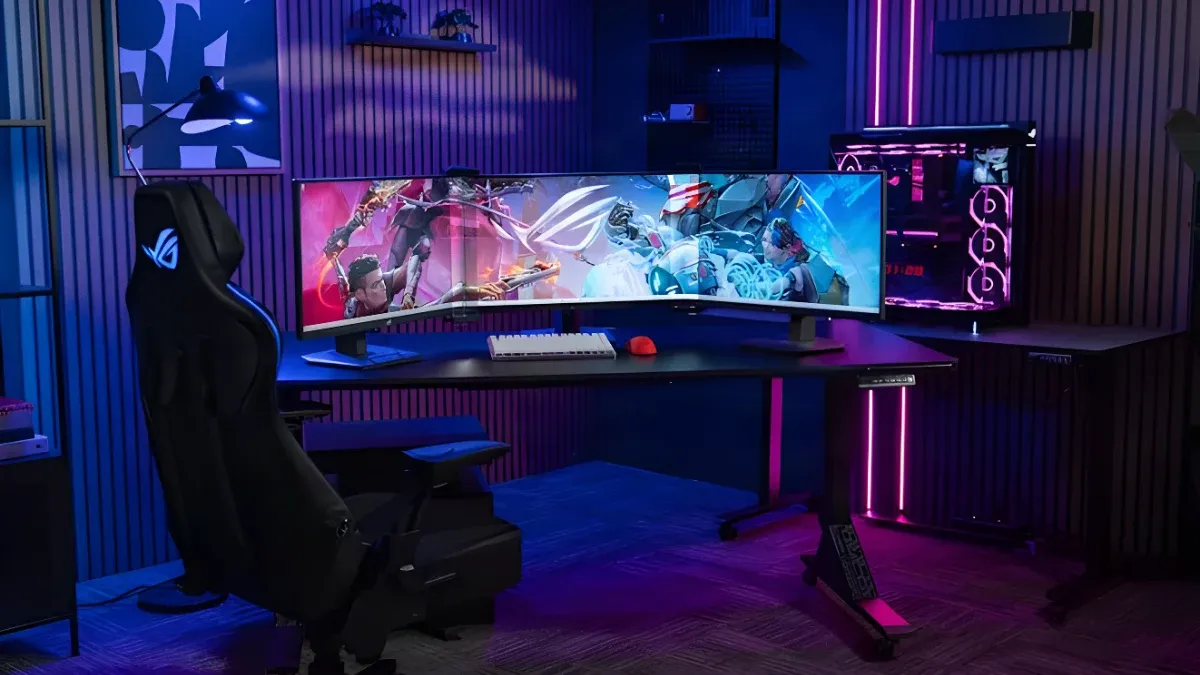
Watch enough movies and you might start to believe that a multi-monitor setup is something exotic—the domain of genius hackers, paranoid supervillains, and hyper-vigilant day-traders.
The truth is that people from all walks of life use multi-monitor setups. It's one of the most practical upgrades you can make to a PC, and it's easy to set up and use. Gamers keep digital worlds front and center while Discord, a map, and a guide sit one glance away. Streamers read chat live and monitor their output without breaking immersion. Colorists keep footage in view while every scope and panel lives on...
Google announced Gemini 4 Argon, a new frontier model rolling out to trusted cybersecurity defenders through its Fairwind Program. Built to handle deep reasoning across complex, long-horizon workflows, Argon delivers frontier performance in software engineering, enterprise knowledge work like legal and finance, and cybersecurity defense.
The company is taking a phased approach to safely release capabilities at this level, actively engaging with the U.S. government's voluntary pre-release model access process while gradually expanding access. Argon will launch at an introductory price of $2...
Ollama now supports decision models based on TypeSafe's Jev API for fast, typed decisions. The new API is available as of Ollama 0.35 using the /v1/systemone endpoint. Send text as state with a set of named questions, and a model running locally answers them all in one request. This is useful for tasks requiring fast decisions, such as ticket triage, model routing, and content or safety moderation.
curl http://localhost:11434/v1/systemone -d '{ "model": "nimble", "state": "Our checkout has returned 500 errors since 9am.", "questions": { "label": { "type": "choice", "instructions": "Which...
Every week, I talk with founders building at an unbelievable pace. Teams are moving from inception to product-market fit faster than ever, with foundation models wired deeply into their core product workflows. Yet as startup architectures mature, a clear divide has emerged between teams struggling with margins and those scaling sustainably. The most effective engineering teams have abandoned the one-size-fits-all model strategy.
In the early days of LLMs, the default architecture was simple: send every interaction to the largest model available. But as applications move into production,...
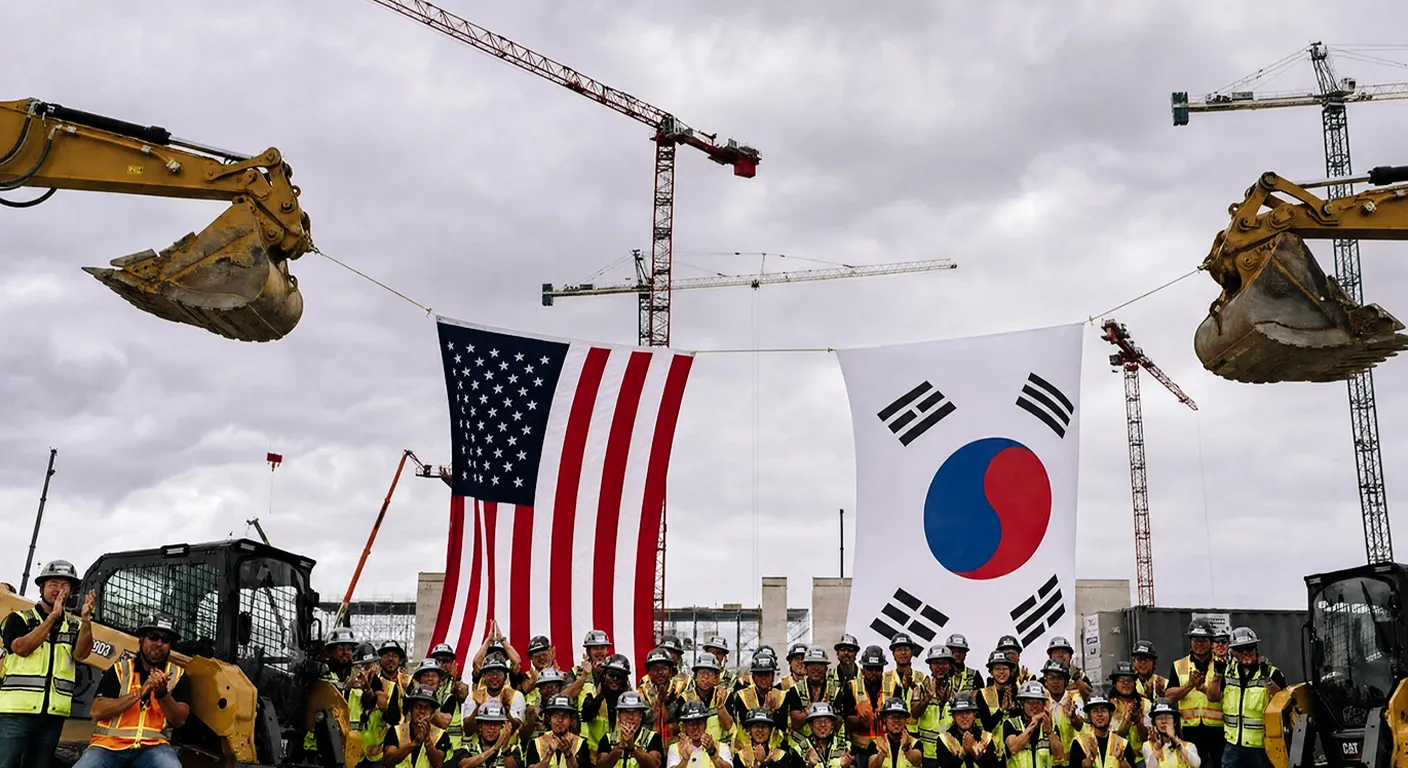
SK hynix held a groundbreaking ceremony on August 27 at Purdue University in West Lafayette, Indiana, for an advanced packaging production facility dedicated to AI memory. The event was attended by Indiana Governor Mike Braun, US Senator Todd Young, Purdue University President Mitch Daniels, and Robert Abrams, Chairman of the Korea-US Alliance Foundation, as well as SK Group Vice Chairmen Yu Jeong-Joon and Lee Hyung-hee, and SK hynix CEO Kwak Noh-Jung. South Korean Ambassador to the United States Kang Kyung-wha also attended.
Attribute
Details
Total investment
Exceeding $4...
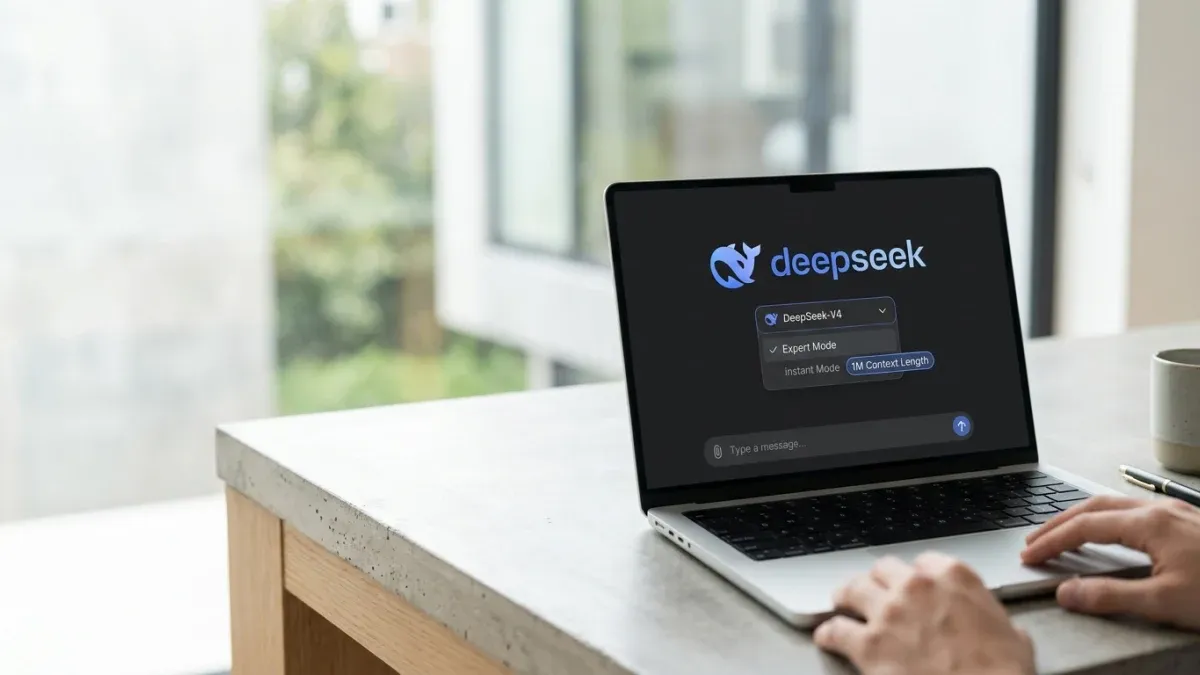
DeepSeek has officially launched DeepSeek-V4, featuring two model variants with 1M context length support. Both are available now at chat.deepseek.com in Expert Mode and Instant Mode, with APIs updated and available today.
Model Specifications
Model
Total Parameters
Active Parameters
DeepSeek-V4-Pro
1.6 trillion
49 billion
DeepSeek-V4-Flash
284 billion
13 billion
DeepSeek-V4-Pro contains 1.6 trillion total parameters with 49 billion active parameters. Its performance rivals the world's top closed-source models.
DeepSeek-V4-Flash contains 284 billion total parameters with 13...
DeepSeek has released V4.1-Flash, the smallest model in its new architecture family, featuring native visual understanding and designed for greater capability, faster inference, and higher throughput.
Asymmetric Architecture Delivers Efficiency
V4.1-Flash is a 552-parameter mixture-of-experts (MoE) model built on a new Causal Encoder–Decoder architecture that uses just 8 billion active parameters for input processing and 16 billion for output generation. The model combines new pretraining methods with larger-scale reinforcement learning post-training to achieve benchmark results that exceed...
Anthropic is introducing Claude Fable 5.1 and Claude Mythos 5.1, positioning them as the world's most advanced models for coding and knowledge work, with research capabilities that offer an early glimpse of how AI models will contribute to scientific progress.
Fable 5.1 and Mythos 5.1 are the same underlying model with different levels of safeguards. Fable 5.1 is generally available, while Mythos 5.1 is available only through Anthropic's trusted access programs, with safeguards specifically designed to support work in cybersecurity and the life sciences.
Alongside increased capabilities,...
Air pollution is a serious public health risk, contributing to an estimated 30,000 deaths in the U.K. alone last year. Data-driven insights can help — but computing air quality with traditional chemistry-based models is expensive, which limits how detailed they can be and how regularly they can be run.
David Topping, a professor in the University of Manchester's department of Earth and environmental science, saw that the NVIDIA Earth-2 family of open AI models and tools had cracked a related problem for weather forecasting and asked whether the same generative frameworks could work for...