ollama

Skip to main content

Tag: ollama

Ollama offers Reflection's Beam free for a limited time

Ollama offers Reflection’s Beam free for a limited time

Ollama is a day-zero partner, rolling out Beam for free for a limited time. In collaboration with Reflection, Ollama's Beam endpoint runs with full zero data retention (ZDR). You can reach Beam through Ollama Cloud, where you can run supported models from your apps or terminal without downloading models or managing local inference. Beam is a mixture-of-experts model with approximately 501 billion total parameters and 23 billion active parameters per token. It is designed for software engineering, reasoning, and long-horizon agentic tasks. Its text-in, text-out design targets workflows that...
Continue reading

Run AI agents safely with Ollama and Fly.io

Run AI agents safely with Ollama and Fly.io

Ollama Cloud now works inside full Linux computers built for agents. Through a new Ollama Connector, code running in Fly.io Sprites can call Ollama's cloud models, including kimi-k3, glm-5.3 and deepseek-v4.1-flash, without the agent ever seeing your API key. A Sprite is a sandbox from Fly.io. Each one is a full Linux virtual machine with its own disk that stays around between sessions. Claude Code, Codex and Gemini CLI are supported out of the box, letting agents run in a sandbox to securely run commands. How the key stays protected You add your Ollama API key to your Fly.io...

Continue reading

Claude Desktop support with Ollama

Claude Desktop support with Ollama

Developers can now configure Claude Desktop to work with Ollama as a third-party gateway provider, allowing them to use open models locally on their computer or access Ollama's cloud models, while retaining the ability to switch back to their existing Claude setup. Connect Claude to Ollama Open Ollama and select Claude, then turn Claude on. Ollama will configure the third-party gateway automatically. You can then choose any model within Ollama—both local and cloud-based. Turn Claude off in Ollama to restore your previous setup. FAQ Will my prompts or data be sent to Anthropic or Ollama?...

Continue reading

Google Cloud logo above text "Startups open up to Gemma" beside a flowing, translucent abstract sculpture in warm hues.

Building Smarter AI Stacks: Why Startups Are Ditching One-Size-Fits-All Models

Every week, I talk with founders building at an unbelievable pace. Teams are moving from inception to product-market fit faster than ever, with foundation models wired deeply into their core product workflows. Yet as startup architectures mature, a clear divide has emerged between teams struggling with margins and those scaling sustainably. The most effective engineering teams have abandoned the one-size-fits-all model strategy. In the early days of LLMs, the default architecture was simple: send every interaction to the largest model available. But as applications move into production,...

Continue reading

Simple black-and-white line drawing of a llama's face with large eyes and upright ears.

Ollama now supports Jev-style decision models

Ollama now supports decision models based on TypeSafe's Jev API for fast, typed decisions. The new API is available as of Ollama 0.35 using the /v1/systemone endpoint. Send text as state with a set of named questions, and a model running locally answers them all in one request. This is useful for tasks requiring fast decisions, such as ticket triage, model routing, and content or safety moderation. curl http://localhost:11434/v1/systemone -d '{ "model": "nimble", "state": "Our checkout has returned 500 errors since 9am.", "questions": { "label": { "type": "choice", "instructions": "Which...

Continue reading

Frontier Intelligence Goes Local

Frontier Intelligence Goes Local

At IFA 2026, NVIDIA, Microsoft and their partners are unveiling faster inference capabilities and simplified tools for running AI agents locally on NVIDIA hardware. New compact NVIDIA RTX Spark Windows PCs arrive in October, offering AI enthusiasts, developers and creators local, secure agent deployment. Simplified Local AI Support and Performance Improvements Simplified local AI support for NVIDIA GPUs is coming to Hermes Agent, OpenClaw and Perplexity Portable Computer. Up to 1.9x faster local inference — New llama.cpp and vLLM optimizations are available now directly through LM Studio...

Continue reading

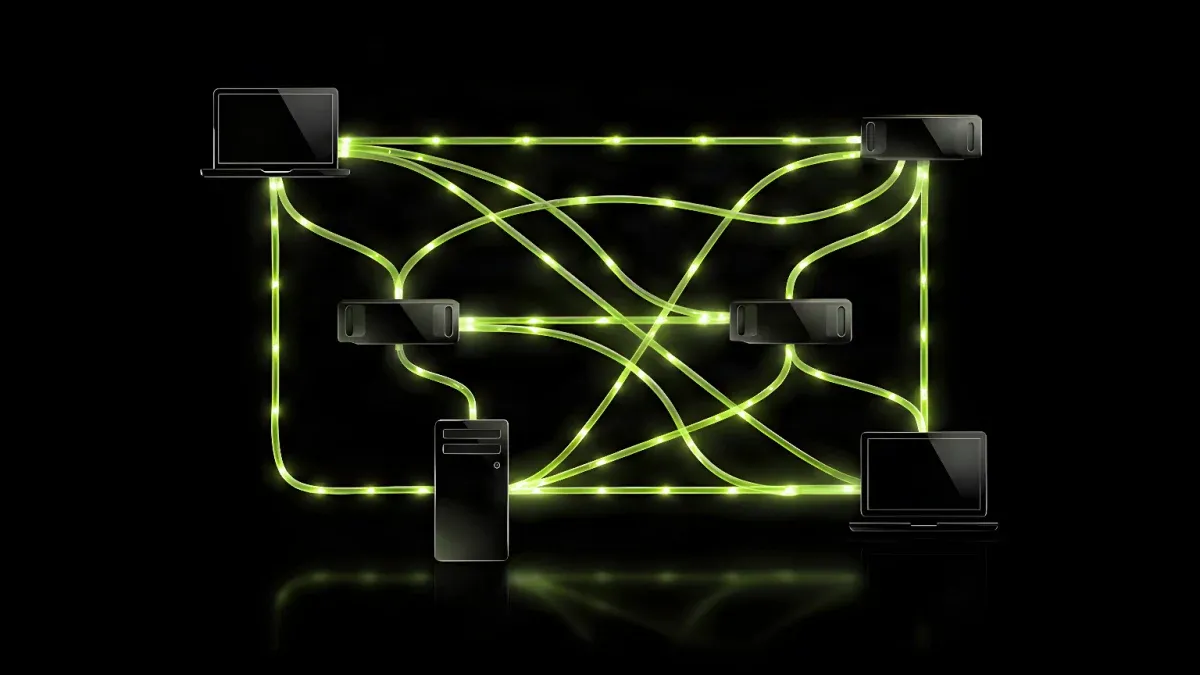
Glowing green network links connect laptops and devices in a distributed system on a dark reflective surface.

NVIDIA PAIR: Distributed AI Inference for Home Networks

AI agents are learning to work together more effectively. A lead agent can break complex tasks into smaller jobs and assign them to specialized subagents, with users increasingly running multiple agent sessions simultaneously. Multi-agent workflows are becoming more common, but this approach can bottleneck the system as many requests flood the GPU at once. NVIDIA Personal AI Router (PAIR) addresses this problem by leveraging local hardware to distribute inference requests across available systems on a home network. PAIR routes each independent request to an available machine and works with...

Continue reading