Two professionals examine performance graphs on a monitor in a server room with NVIDIA hardware.
You're deploying a model on a system. It starts up, prompts are getting responses. Now the hard question: Is this fast?
Your instincts might lead you to send curl commands, hand-roll an asyncio script, or write yet another one-off load generator. All these approaches share the same problems: single-process performance limits, Python's GIL capping concurrency, or numbers measured against a reference you built yourself. Either way, you end up with results you can't fully trust, attached to tooling you'll have to rewrite the moment requirements change.
What you need is a load client that can saturate a real server without becoming the bottleneck, produce actionable output, and take five minutes to configure rather than five hours. That's NVIDIA AIPerf.
AIPerf is the designated successor to GenAI-Perf and is a ground-up rewrite. The design choices reflect lessons from running LLM benchmarks at scale.
A clean break from the old architecture. AIPerf doesn't run on top of Perf Analyzer the way GenAI-Perf did. This architectural separation is why AIPerf can scale effectively. If you're porting an existing workflow, the migration guide covers the key differences.
The client shouldn't be the bottleneck. Most benchmarkers, including GenAI-Perf, use single-process architecture that becomes GIL-bound under real concurrency or request rate. AIPerf is multiprocessed: worker processes generate load, separate record-processor services handle results, and everything is coordinated over ZMQ. This structure prevents AIPerf from becoming a client-side bottleneck, enabling more accurate server benchmarking.
Workload breadth that matches what you actually run. AIPerf supports 15+ endpoint types: chat, responses, NIM rankings, image generation, and more — along with public datasets like ShareGPT and trace replay formats from Mooncake, Baseten, WEKA (AgentX), and others. Whether you're running a quick synthetic smoke test or replaying captured production traffic, you don't need a different tool.
Load shape you actually control. AIPerf supports constant, Poisson, and gamma arrival patterns with tunable burstiness, gradual ramping for concurrency and request rate, and synthetic distributions including vLLM/SGLang range-ratio for variable ISL/OSL. You control the shape of the load, not just the volume.
For this walkthrough we'll use Qwen3-0.6B served through vLLM. The model is small enough to run on a single GPU and fast enough to iterate without waiting. The point isn't to benchmark Qwen3-0.6B specifically, but to establish the measurement loop. Once you have that, swapping in a different model or endpoint is a one-flag change.
Start the server
Pull and start vLLM with the reasoning parser enabled:
docker pull vllm/vllm-openai:latest docker run --gpus all -p 8000:8000 -e HF_TOKEN vllm/vllm-openai:latest --model Qwen/Qwen3-0.6B --reasoning-parser qwen3 --host 0.0.0.0 --port 8000Install AIPerf using uv:
uv tool install aiperfOr in a virtual environment:
uv venv venv source venv/bin/activate uv pip install aiperfOn aarch64, the crick dependency ships as source-only and requires a C toolchain (build-essential on Debian/Ubuntu, Development Tools on RHEL). If the install stalls on that package, install the toolchain first.
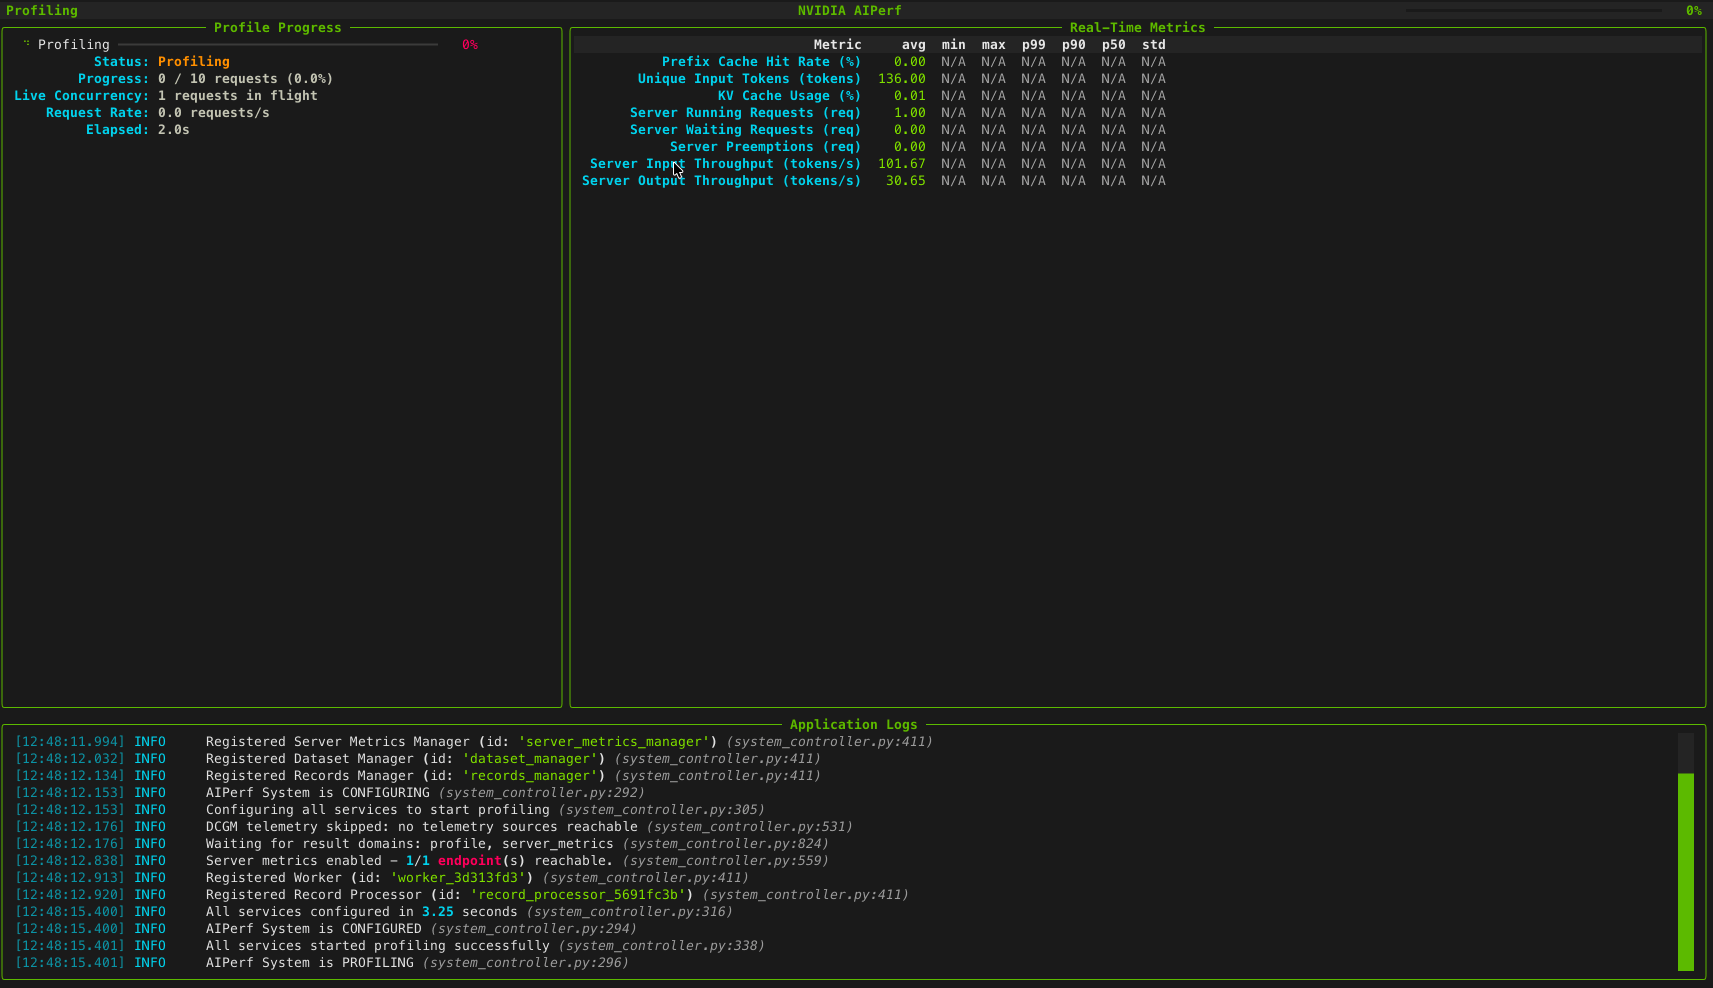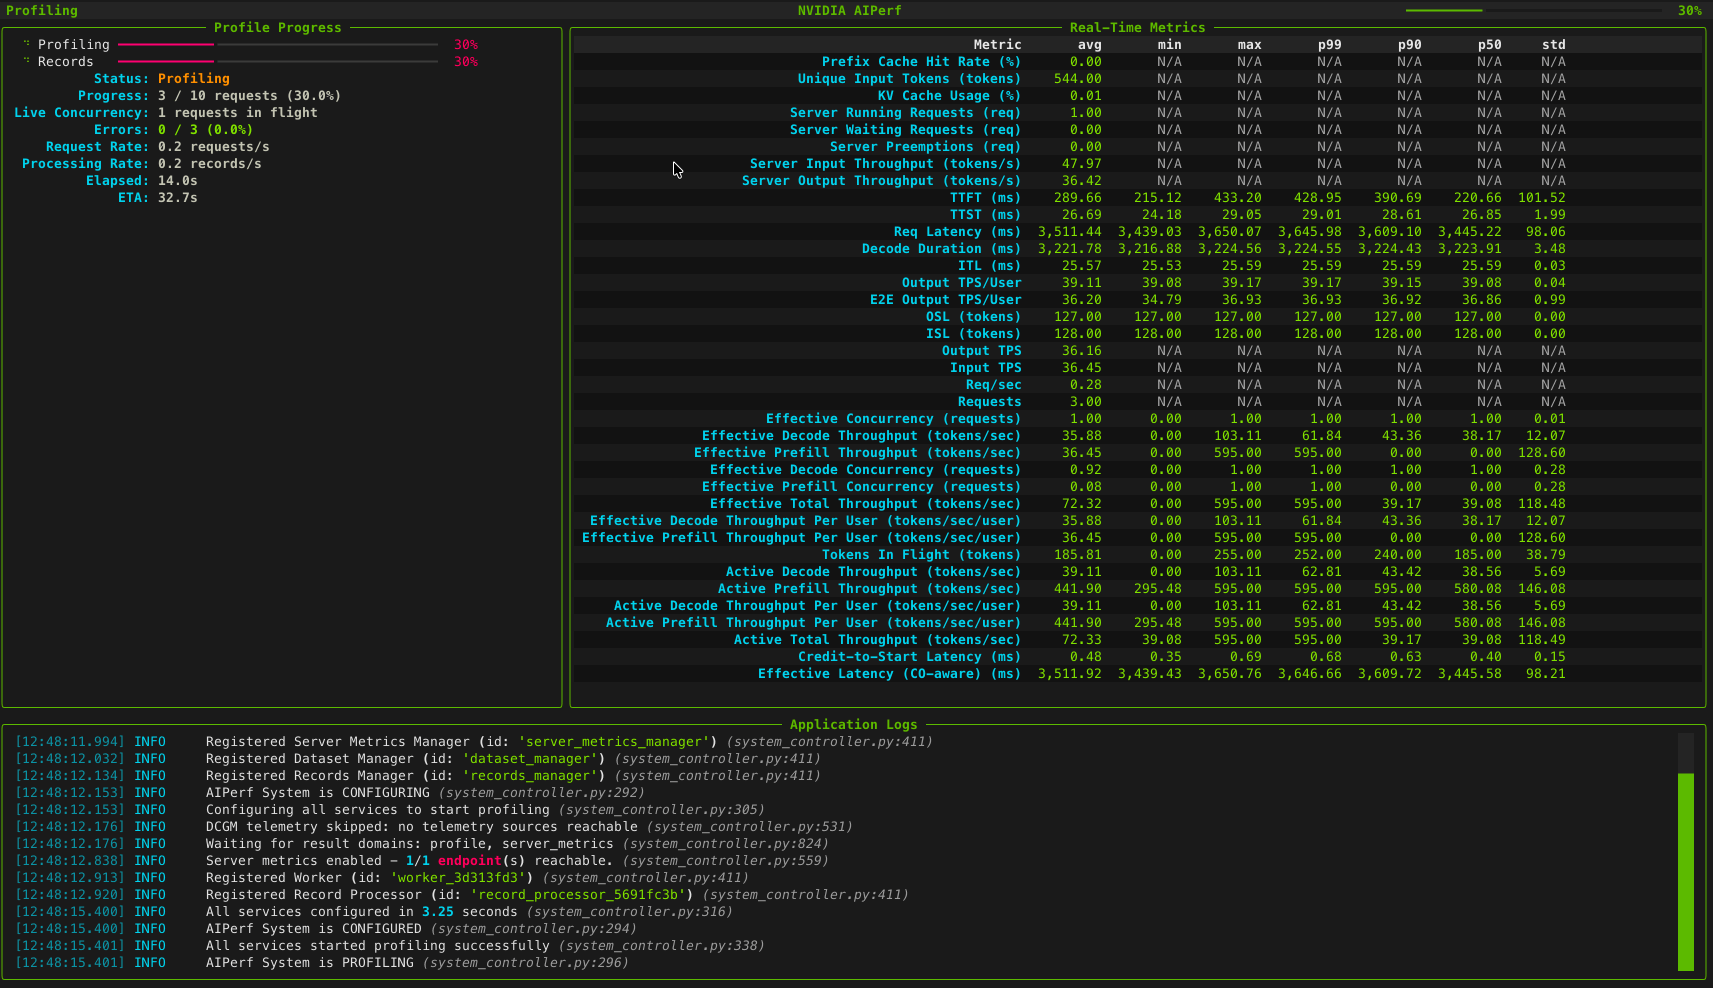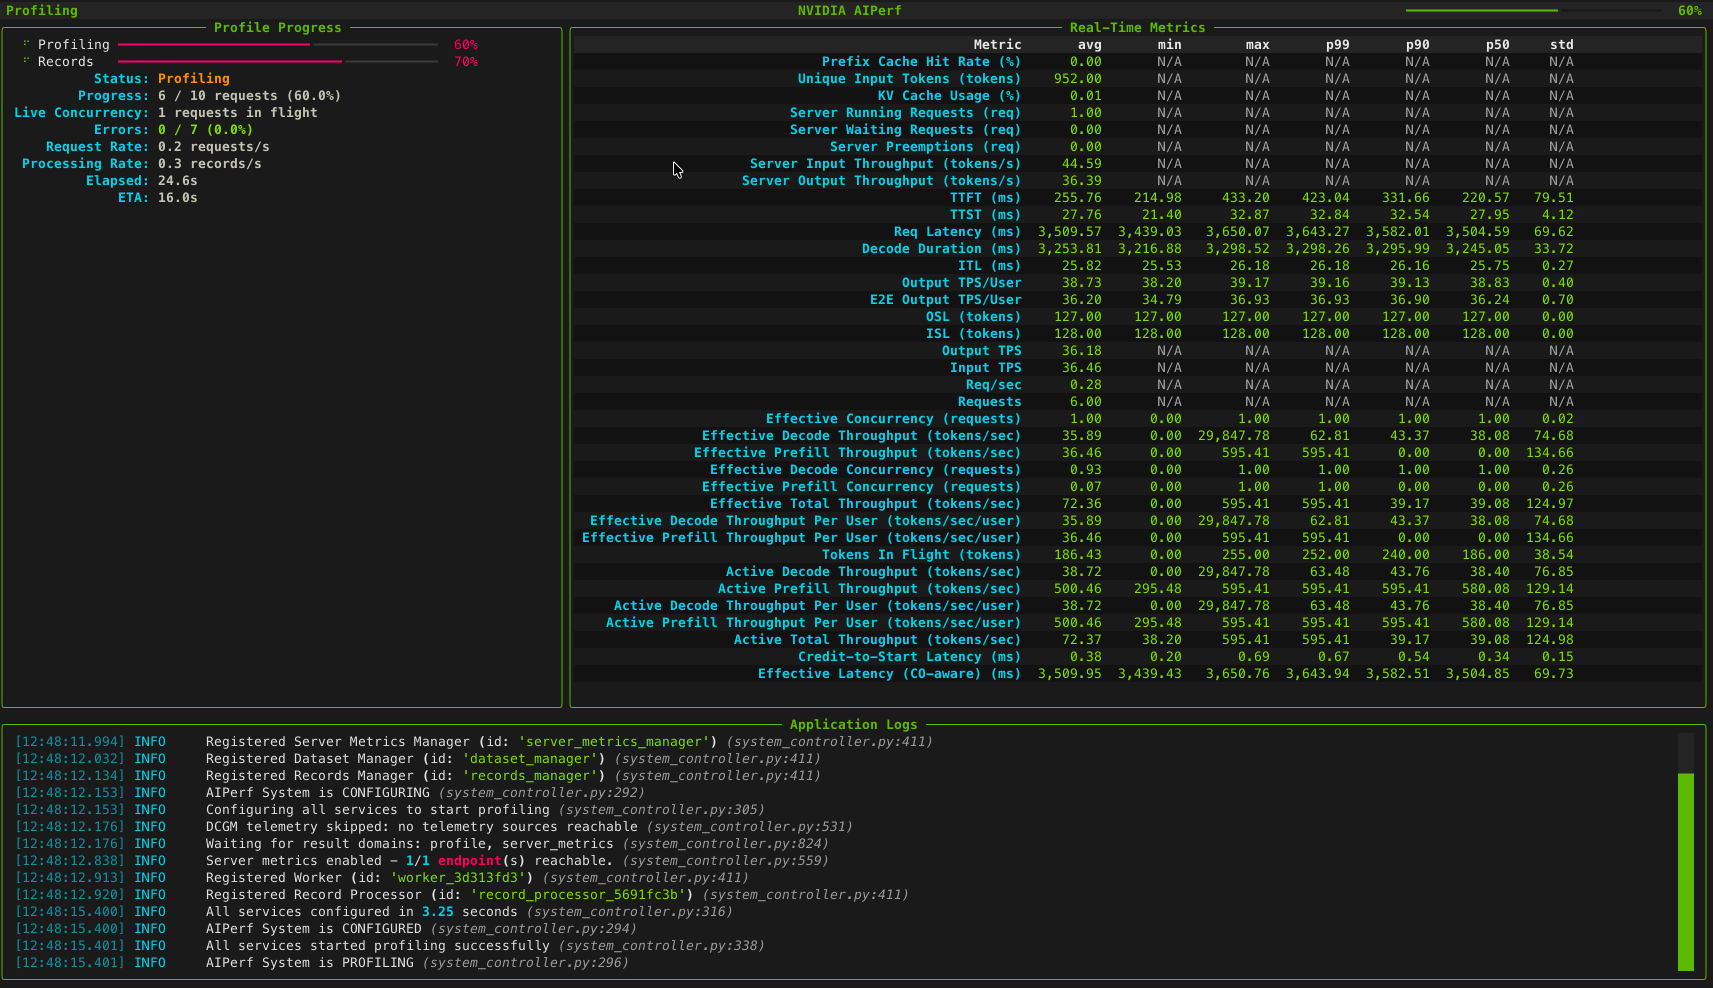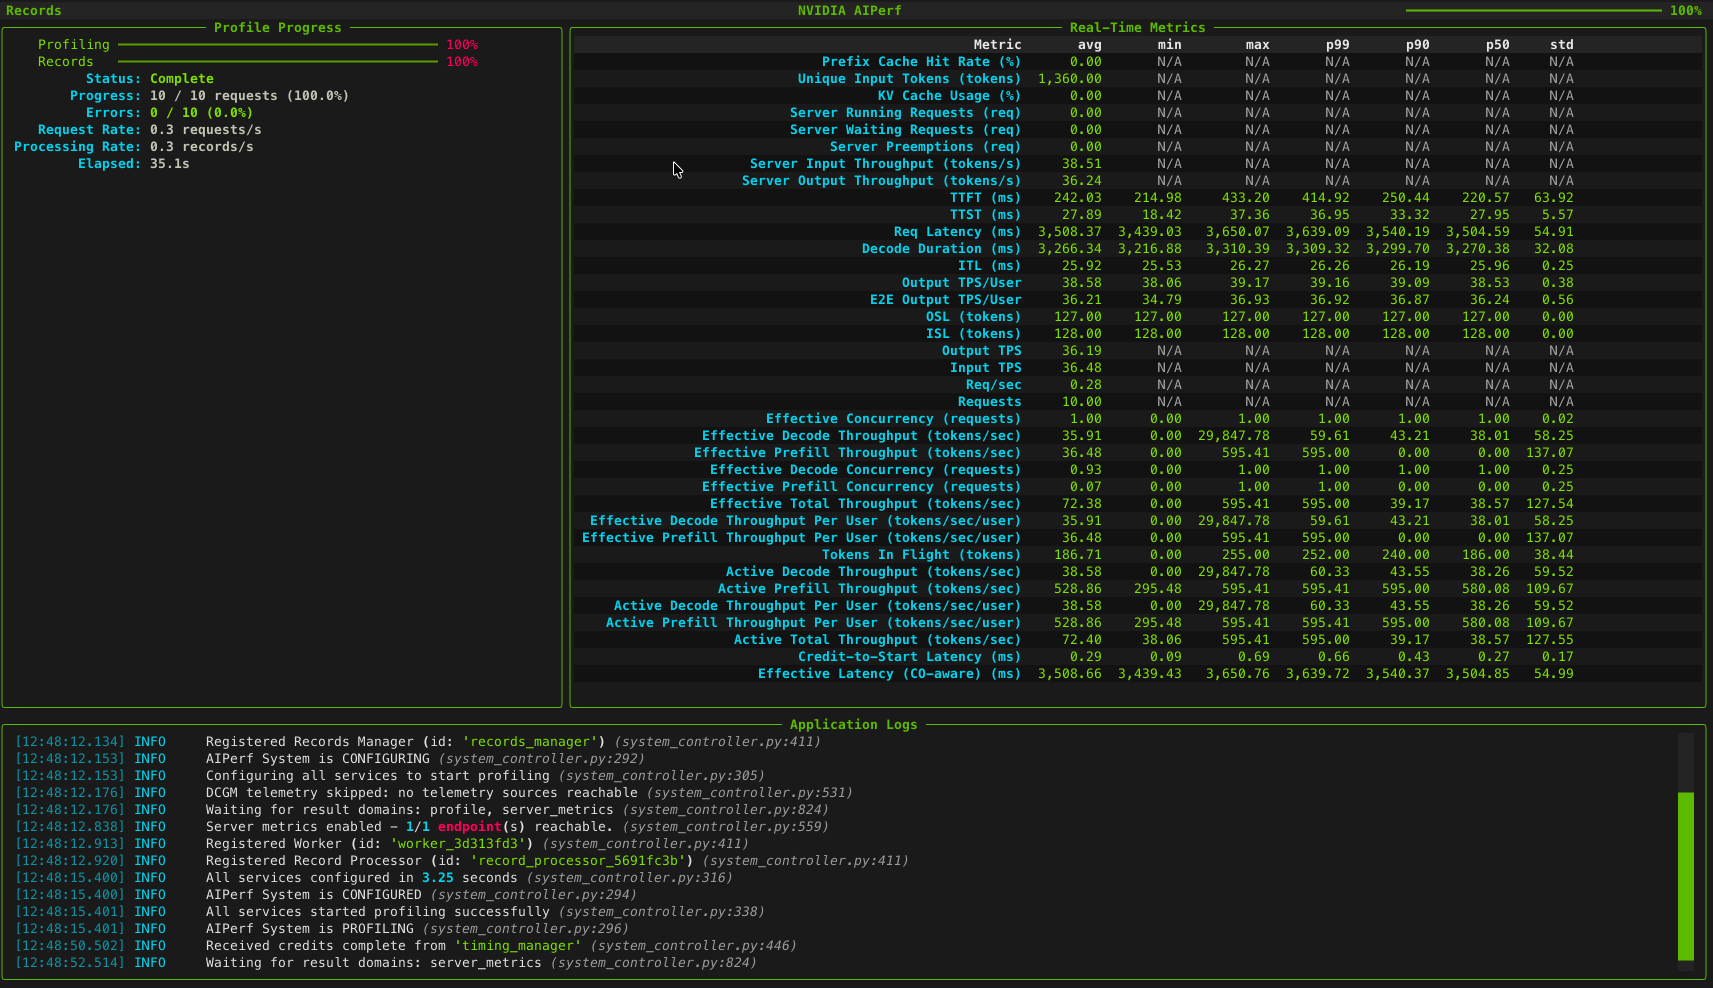
With the server up and AIPerf installed, run your first profile:
aiperf profile --model Qwen/Qwen3-0.6B --endpoint-type chat --streaming --url localhost:8000 --synthetic-input-tokens-mean 128 --synthetic-input-tokens-stddev 0 --output-tokens-mean 128 --output-tokens-stddev 0 --extra-inputs min_tokens:128 --extra-inputs ignore_eos:trueA few flags warrant explanation:
--synthetic-input-tokens-stddev 0 and --output-tokens-stddev 0 pin the workload to exactly 128 input and 128 output tokens per request, reproducing a commonly used static benchmark that holds request and output lengths constant.
--extra-inputs min_tokens:128 and --extra-inputs ignore_eos:true tell the model to emit 128 tokens rather than stopping early. Without these, the output token count is a suggestion, and the model stops whenever it naturally finishes—potentially well short of your target. Throughput numbers end up lower than they should be and aren't reproducible across runs.
--streaming is required if you want to measure TTFT and ITL. Without streaming, the server batches the full response before sending it, leaving no first- or decode-token events to measure.
The live dashboard displays latency broken down by percentile, throughput in tokens per second, and request-level statistics in one place. Once a run completes, AIPerf prints a metrics table to the console and writes full results to CSV and JSON.
The core four:
TTFT (Time to First Token) — How long from request sent to first token received. The primary latency signal for interactive use cases.
ITL (Inter-Token Latency) — Time between successive tokens during generation. High ITL indicates the decode phase is struggling, even if TTFT looks healthy.
Request Latency — End-to-end time for the full response, combining prefill and decode cost into a single number.
Output Token Throughput — Tokens generated per second across all concurrent requests. The primary throughput signal for capacity planning.
For full definitions of these and every other metric AIPerf reports, see the Metrics Reference.
Each metric is reported in percentile breakdowns (p25, p50, p75, p90, p95, p99) alongside minimums, maximums, averages, and standard deviations. These breakdowns matter because they highlight long tail distributions; a server with a healthy mean TTFT but an outlier p99 can fail in production.
With DCGM or pynvml available, AIPerf also pulls GPU power draw, utilization, and memory consumption into the same run output. You can correlate latency spikes with memory pressure events without a separate profiling session.
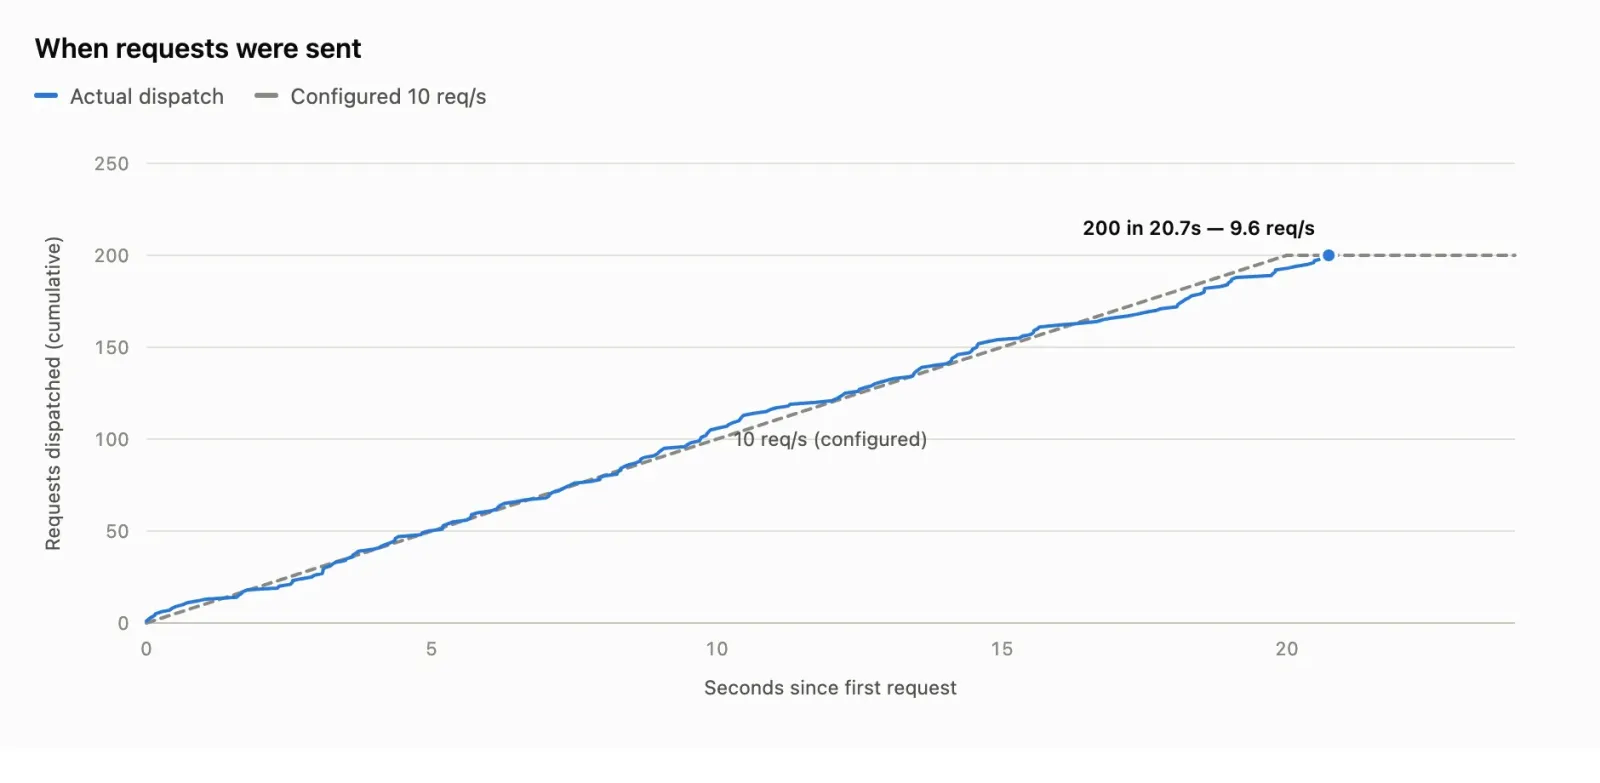
The static benchmark above provides an extremely fixed traffic pattern, but real inference traffic varies. To benchmark with a less rigid scenario, use AIPerf's synthetic workload knobs to introduce variability:
aiperf profile --model Qwen/Qwen3-0.6B --endpoint-type chat --streaming --url localhost:8000 --request-rate 10 --arrival-pattern poisson --synthetic-input-tokens-mean 512 --synthetic-input-tokens-stddev 128 --output-tokens-mean 128 --output-tokens-stddev 32 --random-seed 42 --request-count 200--arrival-pattern poisson with --request-rate 10 means requests arrive at an average of 10 per second, with inter-arrival times drawn from an exponential distribution. The server experiences bursts and gaps rather than a single user stream, emulating real queuing behavior.
--synthetic-input-tokens-stddev 128 introduces variance around the 512-token mean, producing a mix of short and long prompts. The server must handle variable prompt lengths during prefill rather than identical ones.
--output-tokens-stddev 32 adds variance on the output side. Note that min_tokens and ignore_eos are omitted here; in the static benchmark those flags pinned outputs to exactly 128 tokens, but now we deliberately release that constraint so the output distribution can vary.
--random-seed 42 makes the Poisson timing and synthetic length draws reproducible. Rerunning this command produces the same sequence of requests.
Comparing results between the static and dynamic runs shows noticeably wider distributions in the latter—expected when more requests simultaneously compete for GPU access and prefill lengths vary per request. The Poisson run shows a request rate centered around 10 requests/second with natural jitter, whereas the constant mode guarantees exactly 10 requests/second. Input sequence lengths range across a distribution centered on 512 tokens, and TTFT shows much wider spread as multiple requests compete for GPU access while prefill lengths vary and prefill/decode operations overlap.
This walkthrough covers fundamentals, but AIPerf handles more complex scenarios: multi-node Kubernetes deployments, KV cache reuse warm up mechanics, trace replay from production traffic, prefix synthesis, custom datasets, and sweep configurations across concurrency levels.
For distributed inference at scale, see How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale.
Additional tutorials are available in the AIPerf repo.