Tag: nvidia
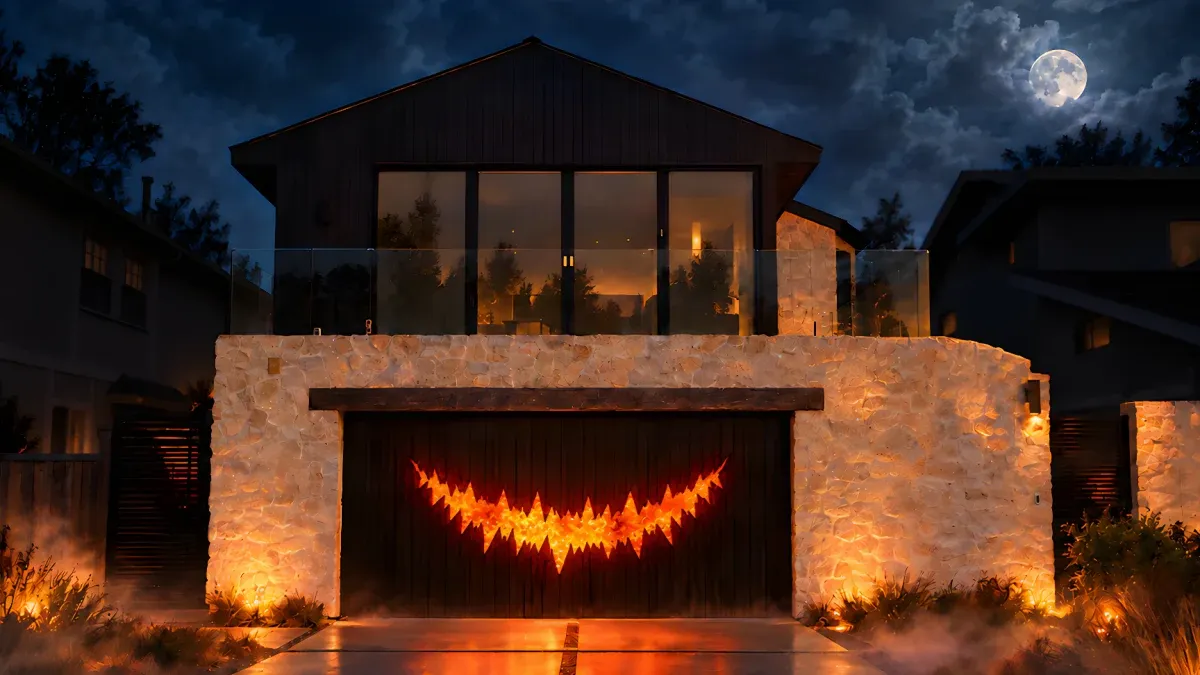
The author built MonsterHouse as an interactive Halloween projection. He listens to trick-or-treaters, answers in the voice of a grumpy old pirate ship, and softens when visitors remember their manners. The project runs on the NVIDIA Nemotron Voice Agent with Nemotron Speech ASR, Nemotron 3.5 Bolt E4B 4GB, Magpie TTS Zeroshot and Audio2Face-3D, all on a single workstation.
The author wanted the kids visiting the house at Halloween to interact in a fun and unique way. The house was going to be in charge and giving out the treats, but more grumpy than scary. Somehow, the solution was to give...
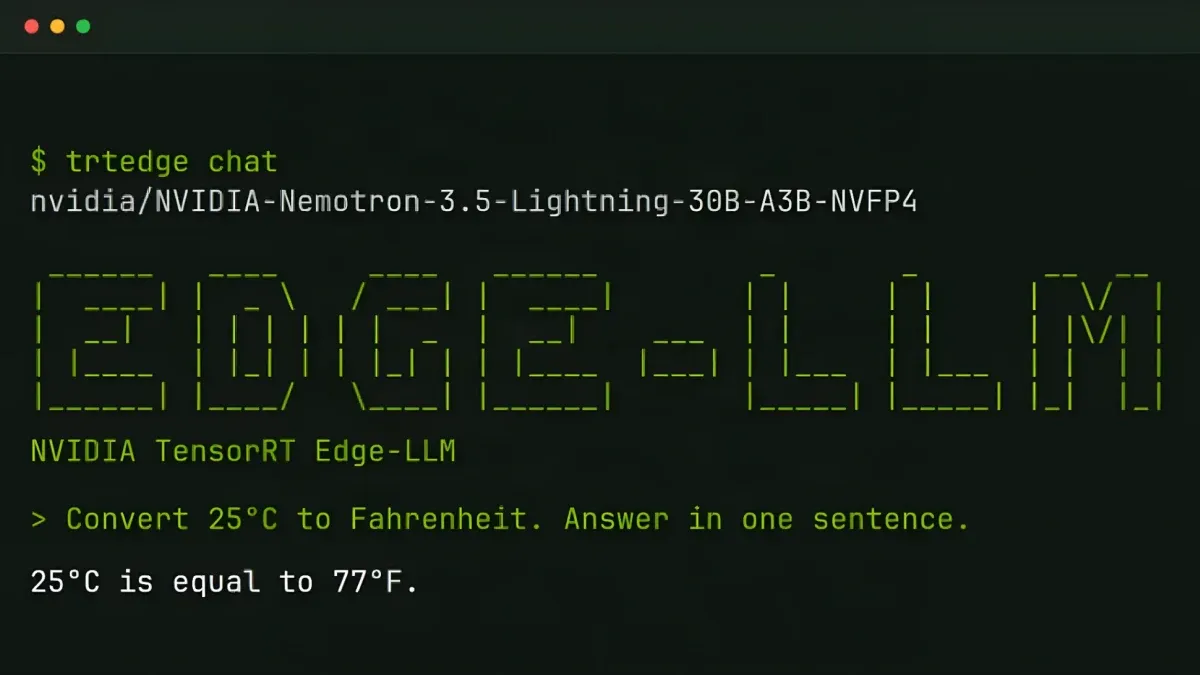
Run Nemotron-3.5 Lightning Locally on DGX Spark
Developers building agents for vehicles, robots, and production lines need models that perceive, reason, and act within tight memory, power, and latency budgets, but getting a model ready to run can involve substantial setup. This tutorial shows how to run NVIDIA Nemotron-3.5 Lightning, a text-only model, on the NVIDIA DGX Spark with NVIDIA TensorRT Edge-LLM, a lightweight C++ inference runtime designed for embedded workloads.
DGX Spark, now available in a 64GB configuration, gives embedded developers a platform to prototype, fine-tune, and test models and agents. TensorRT Edge-LLM brings...
NVIDIA Packs 1 Petaflop AI Into Thin Laptops
NVIDIA's RTX Spark laptops, built on a single Blackwell GPU and Grace CPU superchip with up to 128GB of unified memory, are now sold by ASUS, Dell, HP, Lenovo, Microsoft and MSI. The systems deliver up to 1 petaflop of FP4 AI performance in premium Windows laptops, bringing the CUDA platform, RTX graphics and what NVIDIA calls a personal AI supercomputer into machines designed to travel. The launch comes with a set of software updates for local AI, gaming and creative work, including a new open speech model, a new Liquid AI model family, a new resource management control and a launch-day...
NVIDIA’s open model transcribes 40 languages, labels speakers
NVIDIA has released Nemotron 3.5 Transcribe, an open-weight, promptable speech model that turns recorded audio into text and can also attribute speakers, translate, and answer questions about the recording. Most transcription tools produce a word-for-word record and stop there. A transcript can capture every spoken word and still leave people wondering who said what, how to translate it, or how to spell domain jargon. Multilingual calls, fast-paced meetings, and medical dictation each need different output. Transcribe puts these tasks in one checkpoint and lets developers choose the output...
Eight Spark nodes pool 1 TB of memory
NVIDIA announced official support for eight-node DGX Spark clusters at GTC Berlin, scaling unified memory to 1 TB. Each DGX Spark provides 128 GB of unified memory, so four nodes reach 512 GB and eight nodes reach 1 TB. That capacity opens the door to models that previously wouldn't start on a four-node system, including the full GLM 5.3 (753B) model from Z.ai. The benchmarks show that eight nodes deliver the memory headroom and near-linear training scaling, while the best network topology depends on the workload. Support for eight-node clusters in NVIDIA Sync is coming by the end of the...
NVIDIA Cosmos delivers up to 2x faster inference
NVIDIA has expanded its Cosmos platform with new training tools, simulation checkpoints and Cosmos Data Factory blueprints, aimed at developers building world models, which help physical AI systems understand and simulate the real world. NVIDIA says the platform ranks in the top five on six different open model leaderboards. It pairs the frontier open models with data, training and optimization tools and recipes so builders can scale training data, adapt models, test behavior and optimize performance before deployment.
.abn-galeria .uk-slidenav,
.abn-galeria...
Vercel offers NVIDIA’s Nemotron 3.5 Lightning for free
Vercel's AI Gateway now lists NVIDIA's Nemotron 3.5 Lightning as a free model under the name nvidia/nemotron-3.5-lightning-free. NVIDIA serves the model, and it is aimed at long-running agents, sub-agent work, chatbots, and RAG systems.
Nemotron 3.5 Lightning is an open-weight reasoning and chat model. It has 30B parameters, with 3B active per token. Its hybrid Mixture-of-Experts design interleaves Mamba-2 and MoE layers with a few attention layers. The model has a 1M token context window and supports tool calling and structured outputs. The provider may retain prompts for model...
NVIDIA RTX Spark delivers 4.6x coding agent performance
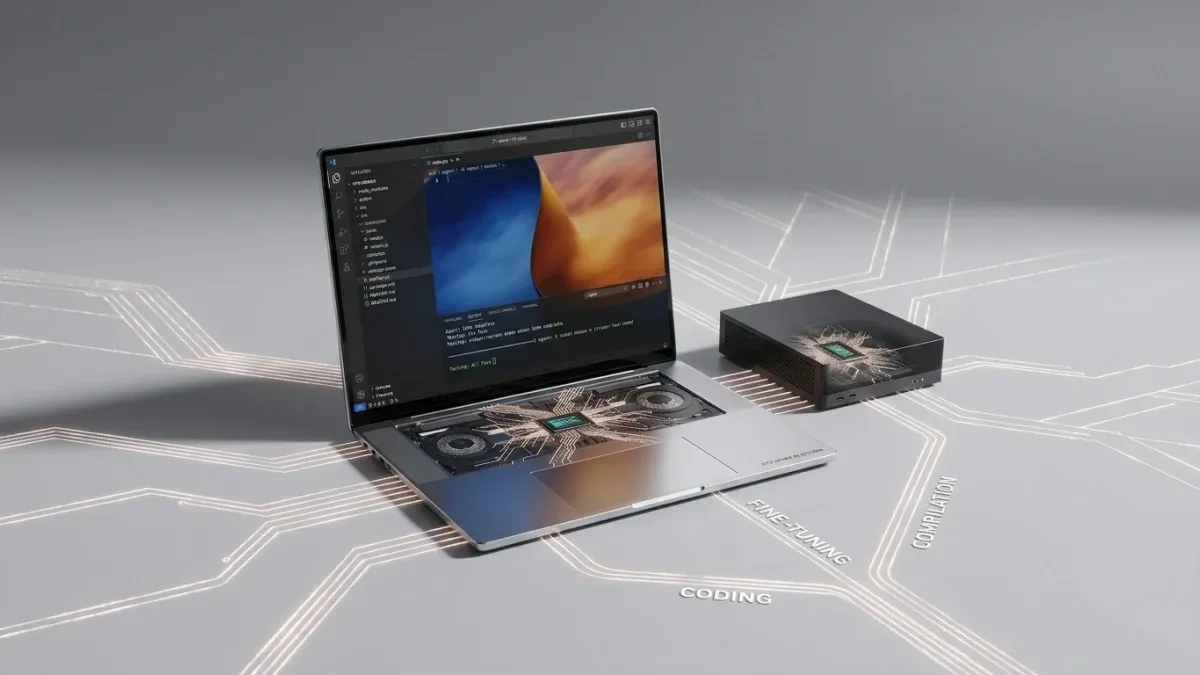
NVIDIA's RTX Spark is a laptop and compact desktop platform built for AI development. Its GB10 system-on-a-chip and large unified memory let developers run local coding agents, access AI frameworks, and code, test, and deploy on a single PC. The workflow that developers now split across a laptop, a cloud model API, and a cloud VM can, according to NVIDIA, be completed on one machine. Compared with Intel's Panther Lake 12Xe, NVIDIA says RTX Spark delivers 4.6x performance on coding agents, 2.7x on fine-tuning, and 1.8x on code compilation.
One machine for the whole workflow
AI agents are...
Windows Hello – Welcome to NVIDIA RTX Spark chip
Microsoft is releasing new Windows 11 Insider Preview builds across its Beta, Experimental, and Release Preview channels, and the release coincides with the launch of a new range of Windows 11 devices powered by the NVIDIA RTX Spark chip. Microsoft says it “never been a better time” to join the Windows Insider Program, and it expects a new group of Insiders and devices to join and help shape Windows.
The builds cover several Windows versions. On the Beta channel, Windows 11 Insiders get Build 26220.9739. The Experimental channel gets Build 26340.9750. Insiders on specific...