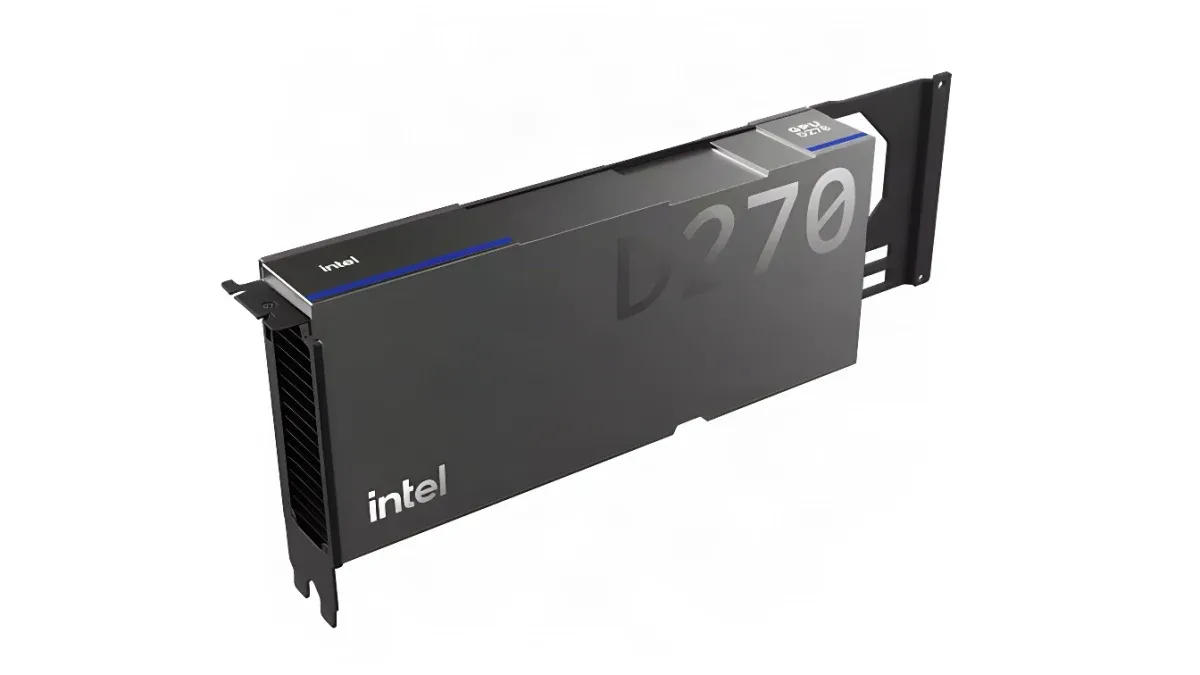
Intel used the Open Compute Project (OCP) Global Summit to share new technical details on the Intel GPU D-series, formerly code-named Crescent Island. The accelerator is built for AI inference on Intel's Xe3P architecture, and Intel positions it as a way to improve the economics of memory-intensive inference. Intel also showed new Intel Xeon-based rack designs and highlighted its open software and ecosystem work. Intel framed these moves around open models reshaping the economics of agentic AI, which is driving demand for more flexible, cost- and power-efficient infrastructure.
Why Agentic AI Needs Heterogeneous Infrastructure
Intel argues that agentic AI turns inference into a multi-step workflow spanning retrieval, reasoning, orchestration, tool use and execution, and that x86 CPUs play a central role in that workflow. Open models give enterprises more choice, but power constraints, memory bottlenecks and cost pressures make scaling AI a systems challenge. Intel's answer is turnkey, heterogeneous infrastructure that is easy to deploy and manage. The company says it brings CPUs, GPUs and specialized accelerators together through open, interoperable software, matching each task to the right compute resources to improve utilization, performance and efficiency across the whole workflow.
Xeon: The Compute Foundation for Agentic AI
Intel showcased new Xeon-based rack designs developed with ecosystem partners. Many leverage the Open Compute Project's Open Rack v3 (ORv3) standard to simplify deployment and integration within open data center infrastructure. Intel says agentic workflows place growing demands on general-purpose compute to orchestrate workloads, process data, manage I/O and execute tasks that keep accelerators productive. To meet that need, select Xeon 6+ configurations scale beyond 46,000 cores per rack at 133.45 kW total rack power, which Intel describes as greater CPU compute density for agentic AI at scale.
Intel also argues that performance for AI infrastructure is increasingly measured by the number of concurrent agents a rack can sustain at target latency. In Intel's framing, Xeon helps maximize that delivered work by keeping data flowing, tools executing and accelerators fed.
Intel GPU D-series: Built for Inference at Scale
The Intel GPU D-series is designed to improve the economics of sustained, memory-intensive AI inference. The GPU combines up to 480 GB of LPDDR5X memory, 1.5 TB/s of memory bandwidth and 1.3 petaflops of FP8 compute within a 350-watt power envelope. Intel says this balance of memory capacity, compute performance and power efficiency reflects its approach to optimizing infrastructure for real-world inference workloads.
The card is designed for large language models, long-context workloads and concurrent inference services. It supports models with up to 300 billion parameters on a single card and more than one trillion parameters in an eight-GPU system. Target applications range from multi-tenant AI services to robotics and other latency-sensitive workloads.
The GPU uses a standard PCIe form factor and an air-cooled design, and it runs on a common Xe software foundation. Intel says this simplifies deployment within existing data center environments and keeps applications portable across Intel GPU platforms, so customers can scale inference without specialized rack or cooling infrastructure.
Anil Nanduri, vice president, AI Products & GTM, Intel Data Center Group, said: “Inference is becoming the defining AI workload, and enterprises need infrastructure that delivers the right performance at the right cost. With Intel GPU D-series, we're focused on making high-capacity inference practical to deploy and economical to scale.”
Intel is working with a broad ecosystem of OEMs, ODMs, neoclouds, independent software vendors, appliance providers and AI-native companies. These efforts focus on validated platforms, software integration and deployment-ready solutions that Intel says will help customers move more quickly from model evaluation to production.
Open Software for Heterogeneous AI
Intel's open software strategy emphasizes native upstream integration with industry-standard AI frameworks, inference runtimes and deployment environments across CPUs and GPUs. Intel says the approach is built on tools developers already use, and it highlights several capabilities:
- Simplified deployment across Intel GPUs: Built on a common Xe software foundation, the GPU D-series supports software portability across Intel GPU platforms, which Intel says helps developers reuse existing applications and reduce the effort of deploying workloads on new hardware.
- Open frameworks and performance software: Intel supports the AI frameworks, serving engines and development tools already used across the industry, complemented by performance libraries and programmable software layers to optimize inference throughput. The same frameworks support inference and agentic applications on Intel Xeon processors.
- Day 0 support for emerging open models: Through upstream framework integration and model enablement, Intel is working to support new open models across the GPU D-series and Xeon processors. Recent efforts include Day 0 support for Meta's Muse Glimmer.
- Built for real-world AI applications and agents: Intel says its software stack supports workloads from high-throughput token generation to coding agents and complex enterprise workflows. The Intel AI for Enterprise Agent Toolkit is optimized and deployable on Xeon processors today, and its provider-based architecture is designed to extend to Intel GPUs.
Open Infrastructure
Intel has made 116 contributions to the Open Compute Project since 2011. At this year's event it is showcasing its contribution to the Open Adapter Card workgroup. Developed with industry partners, the work aims to define a standardized sub-rack accelerator card form factor and improve mechanical, electrical and management interoperability across system designs. Intel says this gives system builders and cloud providers a more consistent path for integrating accelerators into open infrastructure.
Kevork Kechichian, executive vice president and general manager, Data Center Group, Intel, said: “Agentic AI is changing what customers need from their data centers. Success will depend not on any single component, but on open, heterogeneous infrastructure that brings together Xeon, purpose-built acceleration and interoperable software. Intel is helping customers build on their existing investments while creating a flexible foundation to scale emerging AI workloads efficiently.”
Key Features at a Glance
- Memory capacity: Up to 480 GB of LPDDR5X – holds large models and long contexts on one card for memory-intensive inference.
- Memory bandwidth: 1.5 TB/s – feeds the compute units so sustained inference is not starved for data.
- FP8 compute: 1.3 petaflops – provides the throughput for concurrent inference services.
- Power envelope: 350 watts – keeps the card within the power budget of existing data center environments.
- Model support: Up to 300 billion parameters on a single card, more than one trillion in an eight-GPU system – scales from single-card deployments to large multi-GPU systems.
- Form factor and cooling: Standard PCIe, air-cooled – deploys without specialized rack or cooling infrastructure.
- Xeon rack density: Select Xeon 6+ configurations beyond 46,000 cores per rack at 133.45 kW total rack power – adds general-purpose compute to orchestrate and feed accelerators.
Availability
Customer sampling of the Intel GPU D-series is underway, according to the announcement. Intel did not state pricing or a broader release date. Intel invites attendees to visit booth B32 and hear Nic Dubé's keynote, “Put Every Prompt in Its Place,” on October 13 at 10:30 a.m. PT. Intel will also take part in more than 30 technical sessions and speaking engagements.