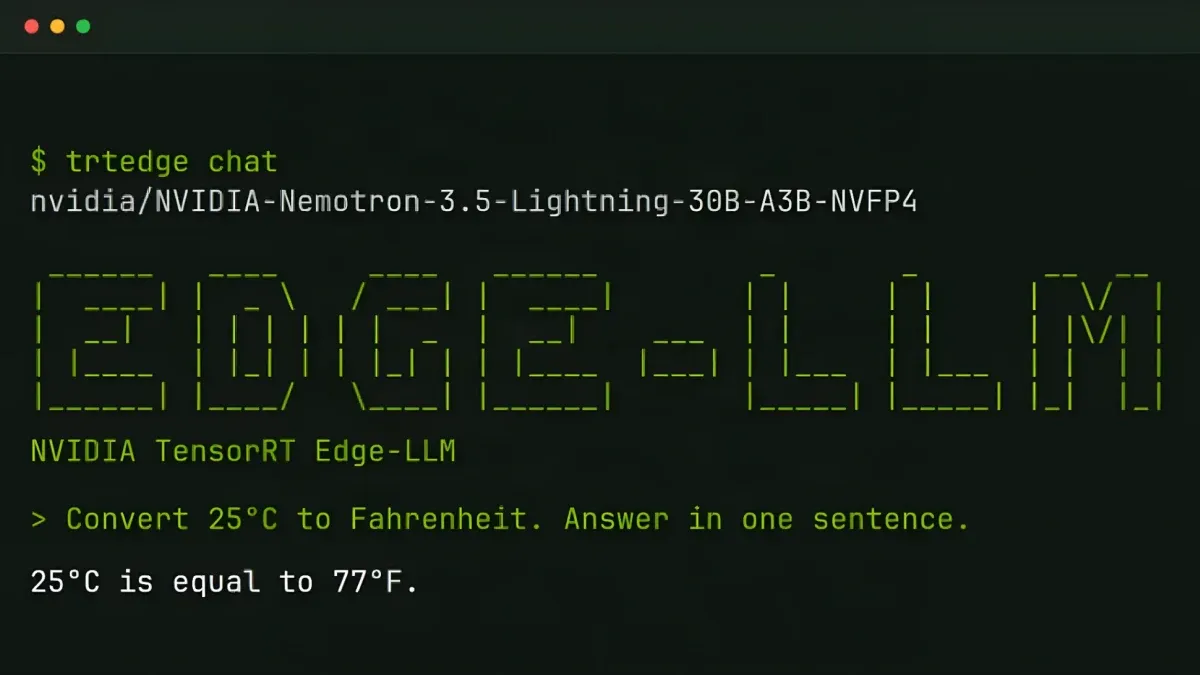
Developers building agents for vehicles, robots, and production lines need models that perceive, reason, and act within tight memory, power, and latency budgets, but getting a model ready to run can involve substantial setup. This tutorial shows how to run NVIDIA Nemotron-3.5 Lightning, a text-only model, on the NVIDIA DGX Spark with NVIDIA TensorRT Edge-LLM, a lightweight C++ inference runtime designed for embedded workloads.
DGX Spark, now available in a 64GB configuration, gives embedded developers a platform to prototype, fine-tune, and test models and agents. TensorRT Edge-LLM brings the same inference framework to development on Spark and deployment on platforms such as NVIDIA Jetson Thor, NVIDIA DRIVE AGX Thor, and NVIDIA IGX Thor. You can get started in just a few commands with the trtedge command-line interface (CLI), which downloads your selected model and builds TensorRT engines optimized for inference on Spark.
In this tutorial, you'll test prompts in your terminal, serve the model through an API for application prototyping, and enable DSpark speculative decoding to accelerate generation.
Prerequisites
You'll need:
- A DGX Spark with a supported NVIDIA software stack
- NVIDIA CUDA 13
- TensorRT 10.16.1.11 or newer within the 10.x series
- Python 3.10 to 3.12
The examples below were tested with TensorRT Edge-LLM 0.11.1 and TensorRT 10.16.1.11.
Install TensorRT Edge-LLM
Open a terminal on your DGX Spark, create and activate a virtual environment, and install TensorRT Edge-LLM:
python3 -m venv --system-site-packages .venv-edgellm source .venv-edgellm/bin/activate python -m pip install --upgrade pip python -m pip install "tensorrt-edgellm[server]==0.11.1"
Note: The virtual environment keeps newly installed packages separate while allowing access to all system Python packages, including TensorRT.
Verify the Runtime
Check the TensorRT version and confirm that the TensorRT Edge-LLM runtime loads:
python -c "import tensorrt as trt; v = tuple(map(int, trt.__version__.split('.'))); assert (10, 16, 1, 11)
The source excerpt ends partway through this check, so the remaining verification steps, the model download and engine build commands, and the prompt and API serving steps are not included here. Consult the full tutorial for those commands.
Takeaways
Use a Python virtual environment with --system-site-packages to install TensorRT Edge-LLM while keeping access to the system TensorRT install.
Pin TensorRT Edge-LLM to the tested version, 0.11.1, and check that your TensorRT version meets the 10.16.1.11 or newer requirement.
The same inference framework runs on DGX Spark for development and on Jetson Thor, DRIVE AGX Thor, and IGX Thor for deployment.