Gemini 4 Carbon – state-of-the-art for cybersecurity
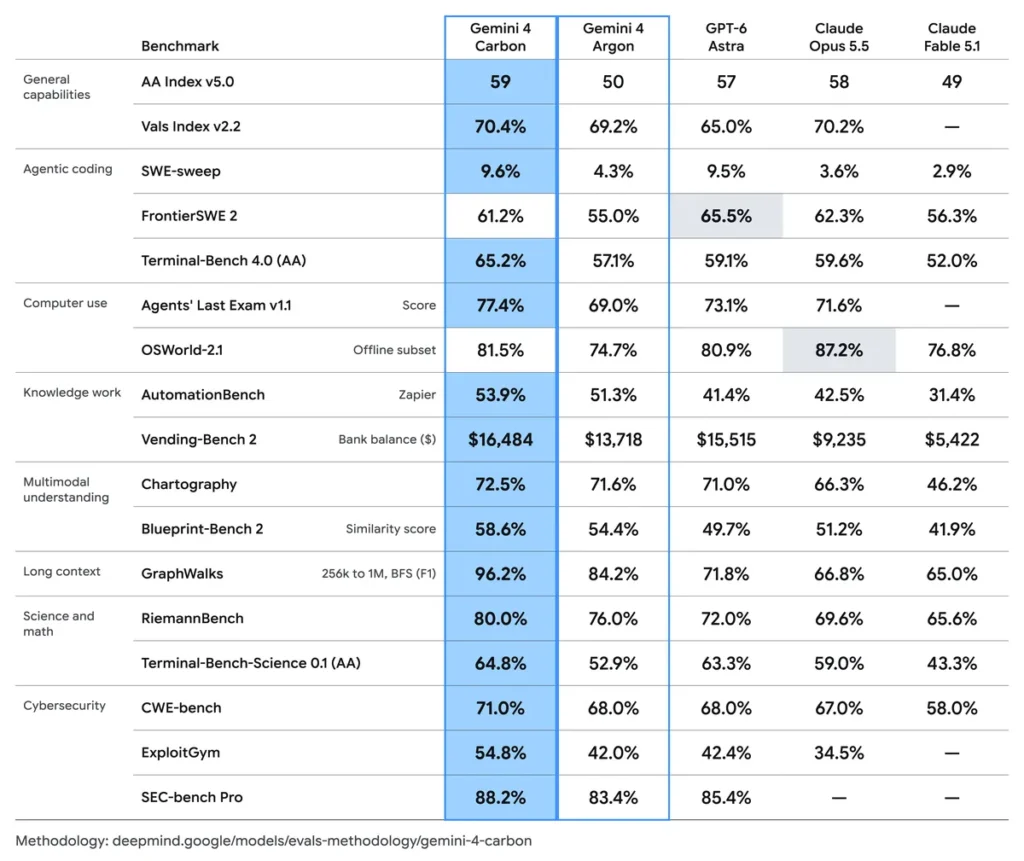
Google has announced Gemini 4 Carbon, its strongest model yet, with state-of-the-art cybersecurity and long-horizon capabilities. Carbon ranks #1 on the recently updated v5.0 of the Artificial Analysis Intelligence Index, where it scores 59. It follows Gemini 4 Argon, which launched two weeks earlier, and Google says the pace shows how quickly it is pushing the frontier forward while strengthening safeguards alongside capability gains.
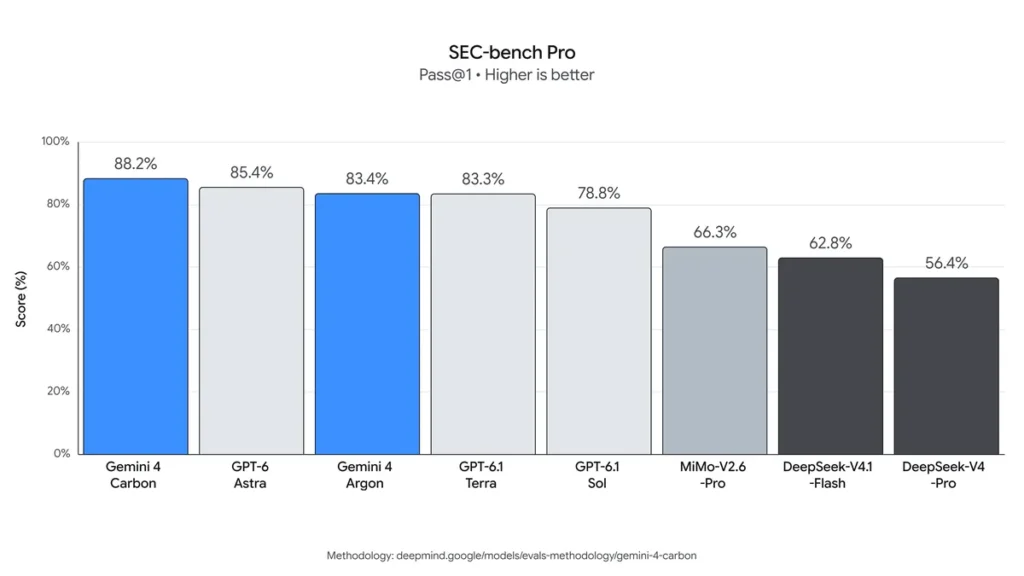
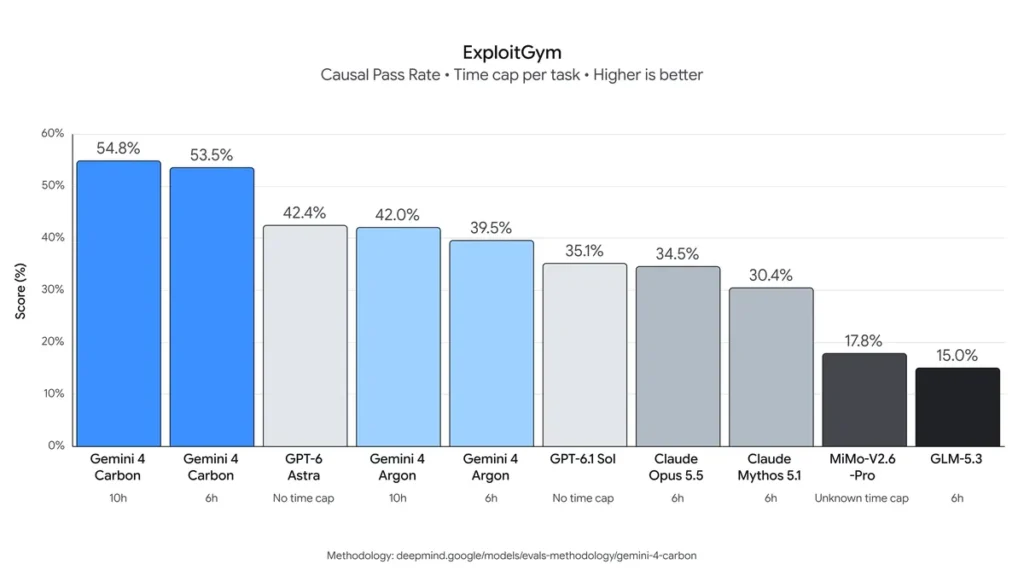
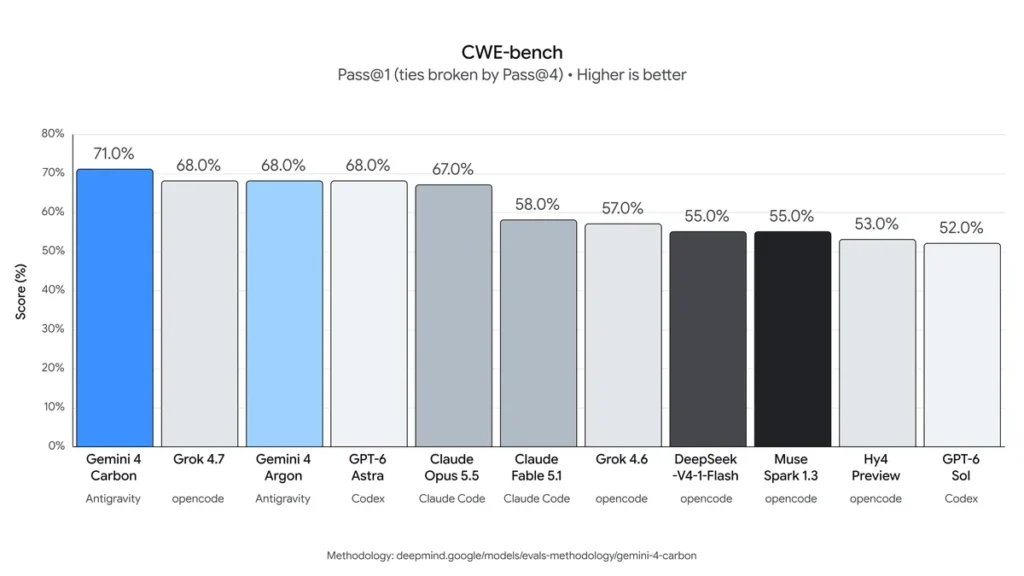
Carbon shows significant gains across coding and agentic tasks, as well as in the capabilities that matter for cyber defense. It takes a firm lead on three security benchmarks: SEC-bench Pro (88.2%) for finding vulnerabilities, ExploitGym (54.8%) for exploitation, and CWE-bench (71.0%) for patching. On Google's internal benchmarks, Carbon produces a strong uplift in generating secure code. In live coding environments with Google's own teams, it shows reduced misalignment and fabrication rates.
Carbon is designed for much harder, long-horizon engineering problems and for sustained agentic workflows. Google's internal teams have seen it run for days, persisting through dead ends to tackle complex, multi-step engineering work. Examples include root-causing and patching subtle bugs across large codebases and low-level systems.
Building on user feedback, Google focused on improving performance across coding, agentic, and scientific tasks, as well as full-stack web development and multimodal understanding. Improved output quality and artifacts in web development lifted Carbon up 89 Elo points, placing it at #4 with a score of 1769 on WebDev Arena.
Google says Carbon delivers a significant leap in cybersecurity and achieves state-of-the-art performance across the defense lifecycle: vulnerability detection, validation, and remediation.
Google also reports real-world signals. On internal benchmarks, Carbon achieves more than 2x uplift in success rate for generating secure code over Argon. The Chrome team reported that Carbon performed more than 10X better than another lab's large frontier model when generating high-quality patches. Wiz, Google's cloud security platform, observes Carbon leading on benchmarks for web penetration testing, a core capability for its Scan for Good initiative. These external results are evaluated without guardrails.
Carbon uses the same multi-layered safety and security stack as Argon, which combines model training, real-time misuse defenses, prompt-injection resilience, and chain-of-thought monitoring. Google says it went a step further on alignment, training Carbon to respond to complex or high-pressure tasks in the right way. Details are in its Safety and Security report.
| Metric | Result |
|---|---|
| Artificial Analysis rank | #1 on v5.0 of the Intelligence Index at 59, showing the model leads overall, not just in one category. |
| SEC-bench Pro | 88.2% state-of-the-art for finding real vulnerabilities, useful for surfacing flaws in production software. |
| ExploitGym | 54.8% state-of-the-art for checking exploitability, helping teams prioritize which bugs to fix first. |
| CWE-bench | 71.0% for patching at the root cause, turning findings into working code fixes. |
| WebDev Arena | #4 with 1769 Elo, up 89 points, reflecting better full-stack web output. |
| Secure code generation | More than 2x success-rate uplift over Argon on internal benchmarks. |
| Terminal-Bench 4.0 cheating | Reduced to 0.0%, with cheating attempts down to 0.4%, signaling more trustworthy agent behavior. |
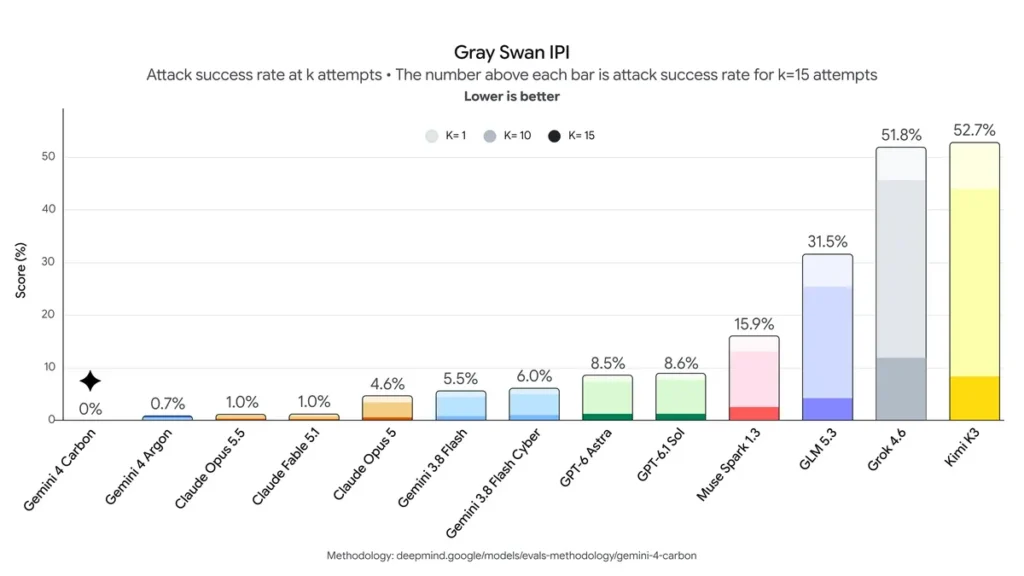
| Prompt-injection resistance | 0.0% attack success on the Gray Swan IPI Benchmark, versus Argon's 0.7%. |
Carbon is rolling out in phases. Starting this week, Google is making it available to a subset of cyber defenders, and it will gradually expand access to additional trusted partners through its Fairwind Program. Google says it is still gathering feedback and iterating on guardrails before releasing Carbon to developers, businesses, and consumers through its product surfaces as soon as possible. Google is also engaged in the U.S. government's voluntary process for pre-release model testing.
Carbon will launch at the same introductory price as Argon: $2 per million input tokens and $10 per million output tokens. Cached input tokens are priced at 95% off the input token price.
| Model | Price | Where to buy | As-of date |
|---|---|---|---|
| Gemini 4 Carbon | $2 / 1M input tokens; $10 / 1M output tokens | Fairwind Program; selected cybersecurity defenders | Oct. 2026 |
| Gemini 4 Carbon | $4 / 1M input tokens; $20 / 1M output tokens | Planned standard pricing | Oct. 2026 |