DeepSeek has unveiled DeepSeek-V4, introducing two powerful model variants that reshape what open-source AI can achieve. With groundbreaking 1M context length and novel attention mechanisms, both the high-performance Pro and efficient Flash versions are now accessible through chat.deepseek.com and live APIs, fundamentally challenging the closed-source model landscape.
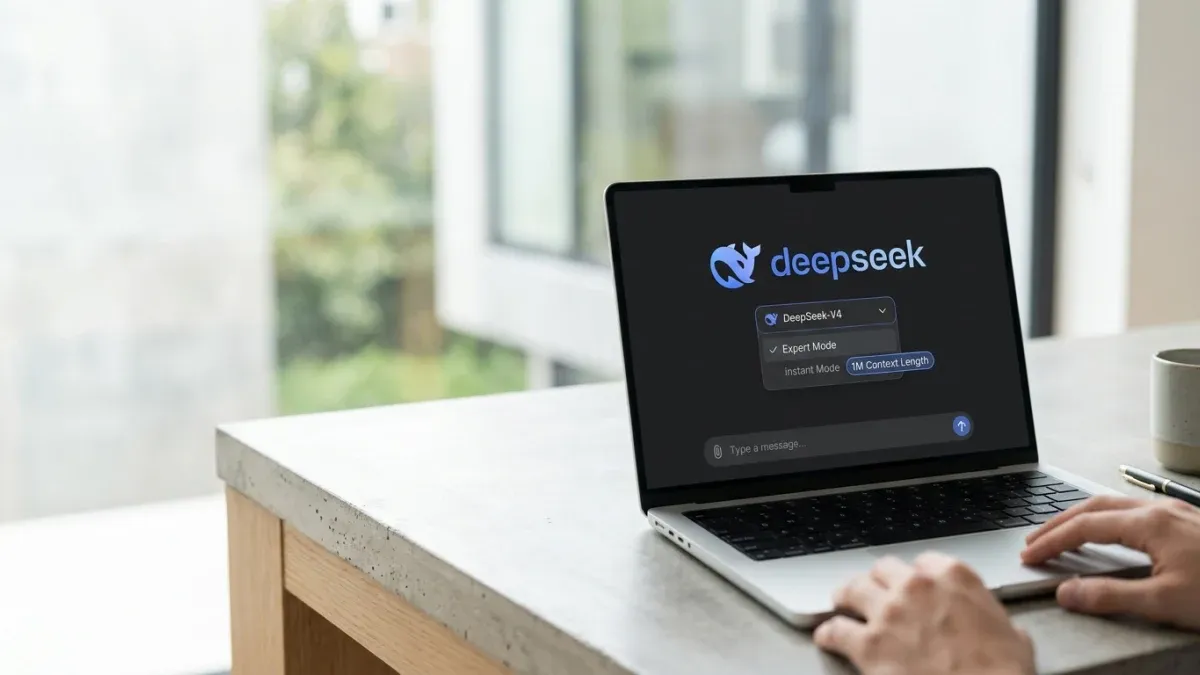
A laptop on a desk displays the DeepSeek interface with model selection and input field, hands resting on the keyboard.
DeepSeek has officially launched DeepSeek-V4, featuring two model variants with 1M context length support. Both are available now at chat.deepseek.com in Expert Mode and Instant Mode, with APIs updated and available today.
Model Specifications
Model
Total Parameters
Active Parameters
DeepSeek-V4-Pro
1.6 trillion
49 billion
DeepSeek-V4-Flash
284 billion
13 billion
DeepSeek-V4-Pro contains 1.6 trillion total parameters with 49 billion active parameters. Its performance rivals the world's top closed-source models.
DeepSeek-V4-Flash contains 284 billion total parameters with 13 billion active parameters, offering a faster, more efficient, and economical option.
DeepSeek-V4-Pro Capabilities
The Pro model achieves state-of-the-art performance in several key areas. It leads all current open-source models in agentic coding benchmarks and in world knowledge tasks, trailing only Gemini-3.1-Pro. In reasoning tasks, it beats all current open models in math, STEM, and coding applications, with performance rivaling top closed-source models.
DeepSeek-V4-Flash Performance
The Flash model's reasoning capabilities closely approach V4-Pro, and it performs on par with V4-Pro on simple agent tasks. Its smaller parameter size enables faster response times and highly cost-effective API pricing.
Structural Innovation and Context Efficiency
DeepSeek-V4 employs novel attention mechanisms combining token-wise compression with DeepSeek Sparse Attention (DSA) to achieve what the company describes as world-leading long-context performance with drastically reduced compute and memory costs. The 1M context length is now the default across all official DeepSeek services.
Agent Integration
DeepSeek-V4 is integrated with leading AI agents including Claude Code, OpenClaw, and OpenCode. The company reports that both models are already driving its in-house agentic coding development.
API Details and Pricing
The API supports both OpenAI ChatCompletions and Anthropic APIs. Developers can update their model parameter to deepseek-v4-pro or deepseek-v4-flash while keeping the existing base URL. Both models support 1M context and dual modes (Thinking and Non-Thinking), with a guide available in the API documentation.
The legacy models deepseek-chat and deepseek-reasoner will be fully retired and inaccessible after July 24th, 2026, at 15:59 UTC. Until then, they will route to deepseek-v4-flash.
DeepSeek also noted that users should rely only on official company accounts for news about the service, as statements from other channels do not reflect the company's views. The company reiterated its commitment to “longtermism” and advancing toward its goal of artificial general intelligence.